 Andrei Kalamkarov
When AI breaks what it’s trying to fix
In our university’s thirteen-year-old CMS, some things that looked wrong were there for a reason.

Our university CMS turned thirteen in August. It runs on Adobe Experience Manager (AEM), holds about 98,000 live pages, and more than 300 people author content in it. For the past two years, we’ve been using AI to help modernize it. Our current tools include Claude Code, Cursor, and Codex.
The failures I want to talk about came out of that modernization work: changes that looked correct but broke behaviour the system relied on. AI’s advice played a direct role in some of them. Others exposed assumptions a developer could make too. The old behaviour looked like a mistake, but it was a contract, something the system relied on. In a system this old, with this many components and decisions behind it, a lot of the reasoning was never written down, or only partly. Without that context, both people and AI can miss what a seemingly sensible change needs to preserve.
The HTML tags that printed as text
This one was easier to spot than the others, but only if you happened to look at a heading where an author had used HTML.
We converted our accordion component to HTL, the modern templating language on our platform. Unlike our old JSP template, it treats HTML in a heading as text rather than formatting. That’s a standard security precaution, but our authors had been using HTML in those headings for years.
After the conversion, the tags appeared on live pages. Headings without HTML looked unchanged, which made the problem easier to miss.

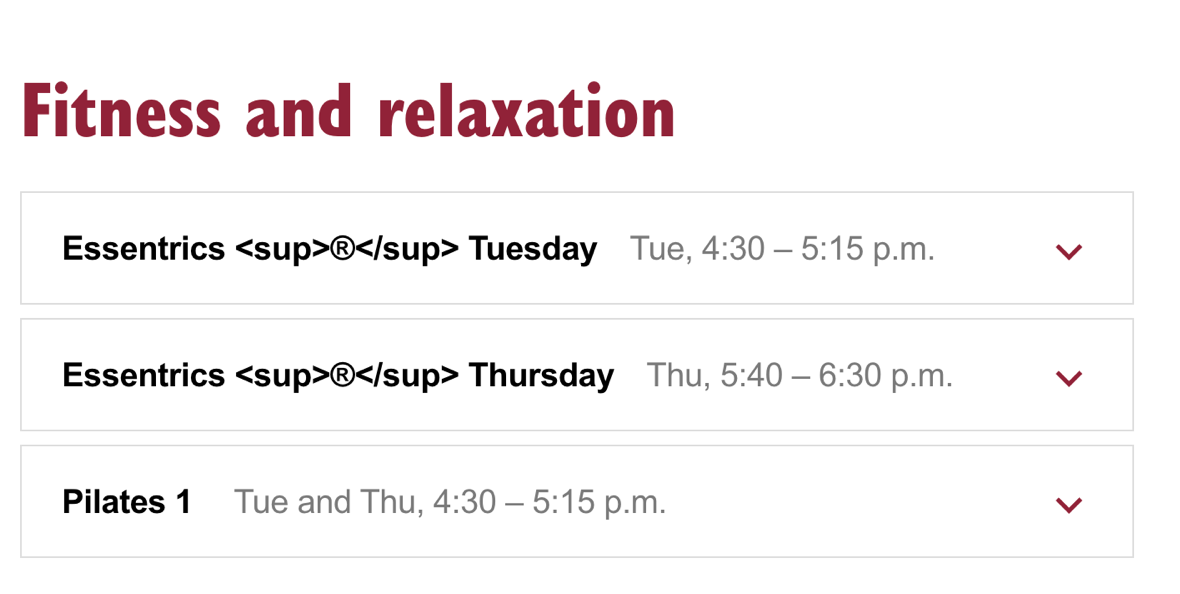
Here’s what had actually been going on. For years, authors had been typing HTML into plain text fields because it worked and let them add formatting the fields didn’t otherwise offer, for example, italicizing part of a phrase or putting a symbol in superscript, like this®. It was one of those hidden tricks some people knew about, rather than a feature we advertised or encouraged everyone to use.
When I ran a query afterwards, 1,425 of 60,790 accordion panels (about 2.3%) had HTML in their headings. We tested many pages, but still missed the particular headings affected.
The uncomfortable part is that the change followed standard security advice, but it removed formatting our content editors relied on.
This is institutional memory: the decisions and workarounds people remember, even when the code doesn’t explain them. At CMS Connect 2026 in Montréal, Matt Garrepy of CMS Critic put it this way: “Memory is becoming infrastructure.” For us, that meant writing this knowledge down for people and for AI.
One part of our approach is a shared instruction file in the code repository, which our AI coding tools read at the start of each session. It holds project decisions and checks we would otherwise have to explain again. We made this instruction apply beyond the accordion, so the AI would check how fields were being used in other components before changing their output.
I’ve shortened the excerpts here for readability. The full entries include more specific technical guidance. Here’s the first:
Some fields allow HTML on purpose, so do not blindly escape them. Certain dialog fields, notably titles and headings, intentionally contain author-entered markup like
<i>,<em>, or<span>. Our old JSP templates emitted these raw, but HTL escapes by default, so a JSP to HTL conversion can silently break the intentional markup. Before changing how a field is output, check whether it is meant to carry HTML.
Technical instruction (abridged)
Some fields allow HTML on purpose, so do not blindly escape them. Certain dialog fields, notably titles and headings, intentionally contain author-entered markup like <i>, <em>, or <span>. JSP emits these raw via <%= %>, but HTL escapes by default, so a JSP → HTL conversion can silently break the intentional markup (an <i> renders as the literal <i>). Before changing how a field is output, check whether it is meant to carry HTML, and use @ context='html' for rich-text or inline-markup fields. Reserve unsafe for trusted full passthrough. This bit the Introduction component after its HTL/Sling conversion, until its title was output with @ context='html'.
Notice what kind of instruction this is. It’s a prohibition with a check attached: don’t escape blindly, look first.
The single space that hid a heading
This one took longer to come to our attention. A single space entered in the component’s title field had been keeping an unwanted heading off the page. The conversion brought that heading back.
Three months after the conversion, our web designer, who knows these pages well, pointed out that headings were appearing where they shouldn’t have been. This was our Introduction component, one of our oldest, in use across the site since 2013. When we investigated, we found that 539 of its 15,421 instances (about 3.5%) had a title containing just a single space.
By default, adding the Introduction component to a page displayed the page title as a heading. Before there was an option to hide it, entering a single space in the title field was a workaround: it replaced the default title with something invisible.
As part of modernizing the component from JSP to HTL, we changed how the title was checked. The new code removed whitespace before checking whether the field was empty. A single space now counted as empty, so the component displayed the page title again.
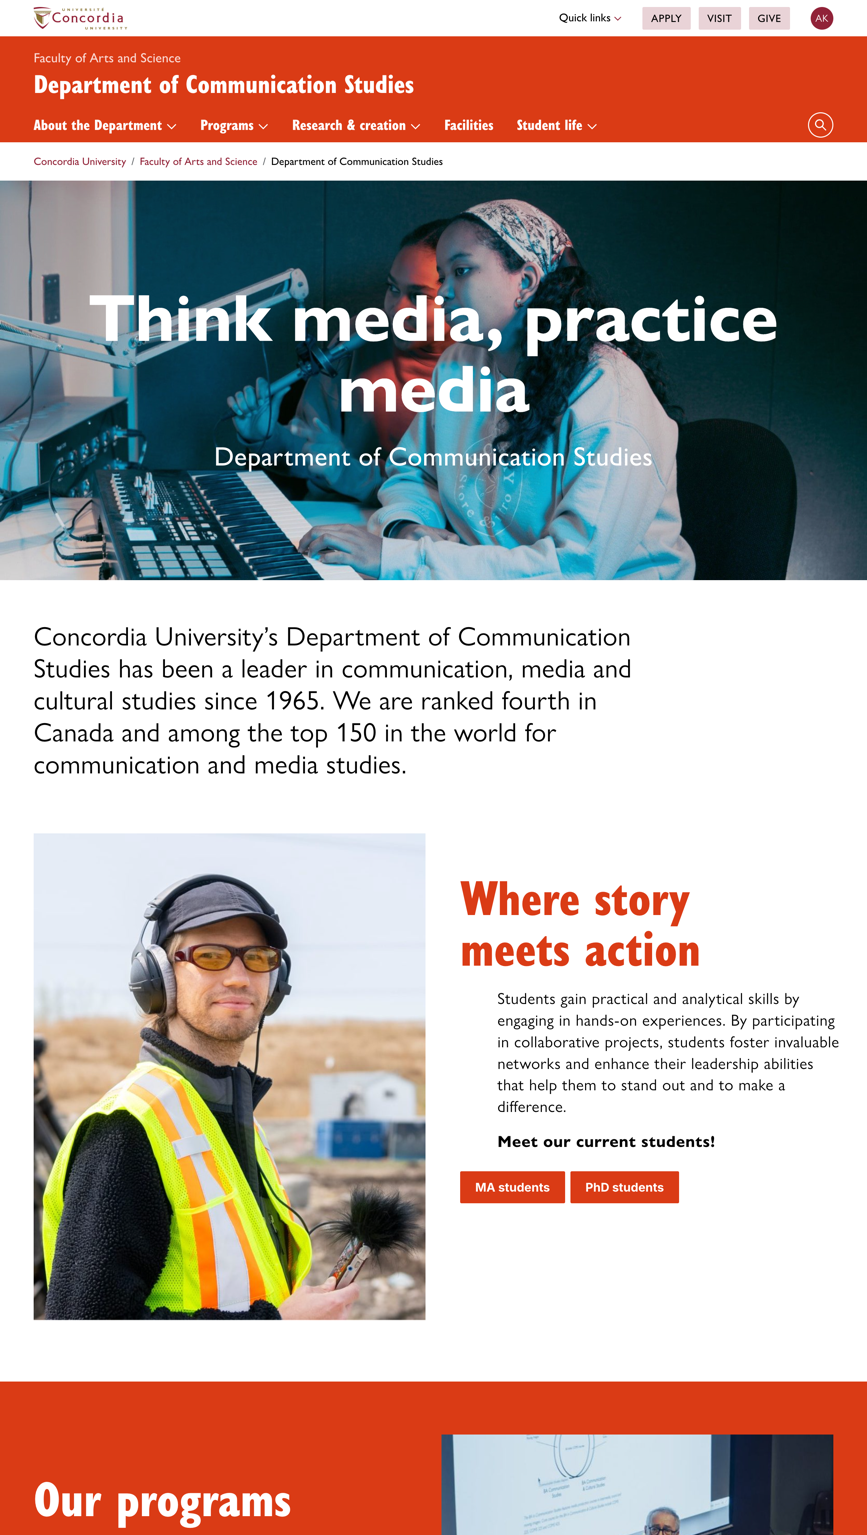
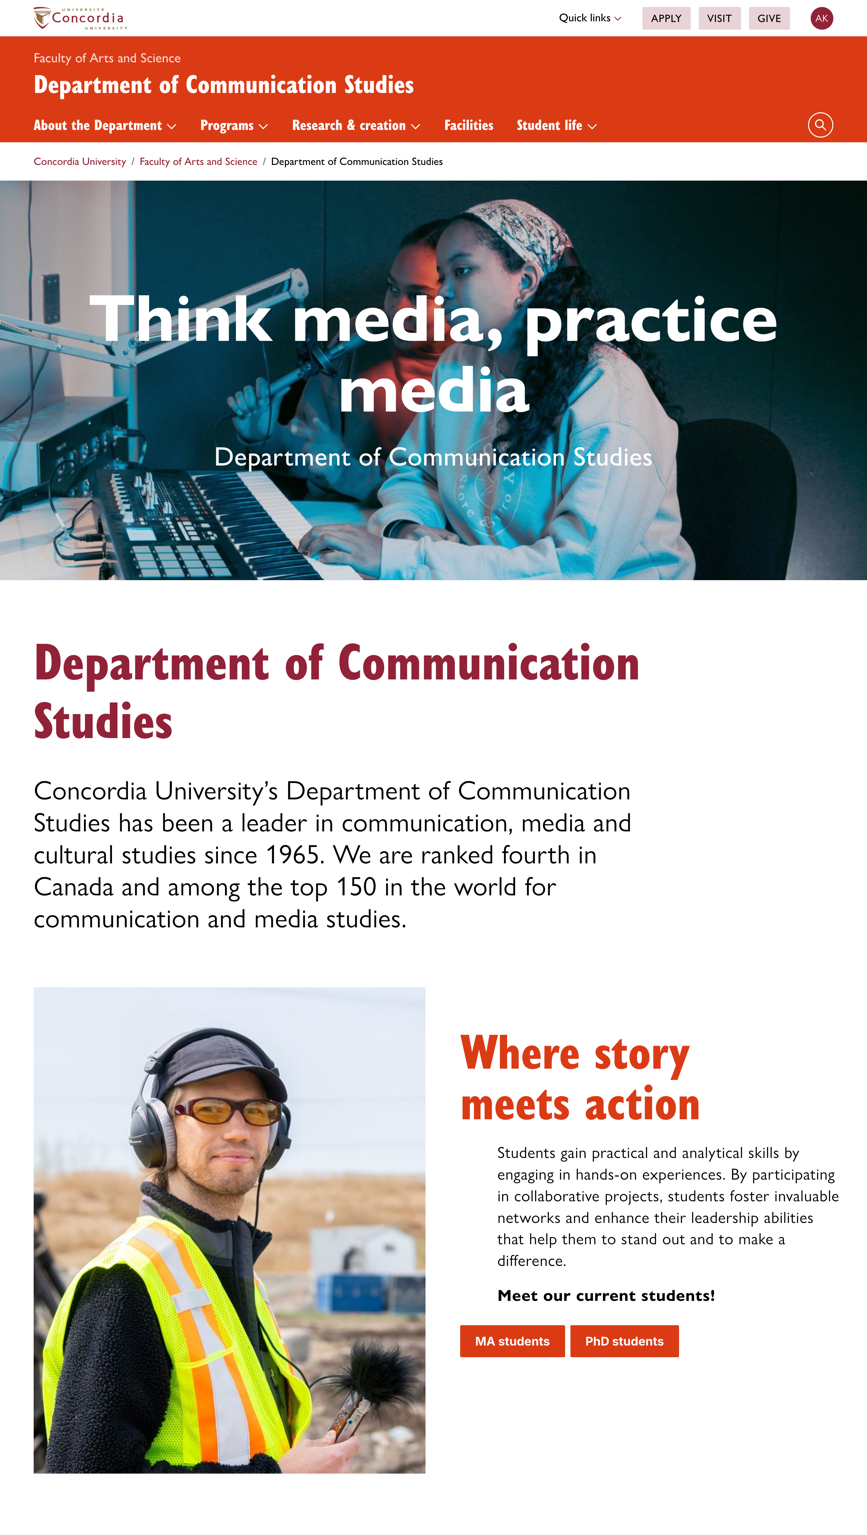
The old code preserved the space, but didn’t explain why it mattered. Investigating the unwanted headings brought that context back to our attention.
When I ask an AI to modernize a component, trimming whitespace is the kind of cleanup it might reasonably suggest. But the saved content matters too. In this case, preserving the component’s behaviour meant understanding how a single space was being used, not just what the code did with it.
So this one went into the file too. Here’s a shortened version of the entry:
Don’t assume an unusual field value is a mistake. A single space, for example, may intentionally suppress a heading. Before trimming or normalizing a value, check what behaviour depends on it. Preserve that behaviour and flag the workaround for review before changing it.
Technical instruction (abridged)
Don't "clean up" sentinel values during JSP → HTL conversion. Legacy components often overload an ordinary field with a magic value that triggers behaviour the dialog never advertises, so the obvious best-practice rewrite can silently delete a load-bearing contract.
- Canonical case: the Introduction component used a
titleof a single space (" ") to hide the title row. The JSP fell back to the page title only whentitlewasnullor"", never when it was" ". - The trap: the clean rewrite (trim the value, then check
isBlank) looks correct but breaks it, because" "trims to"", the page-title fallback fires, and the title shows instead of hiding. - The rule: when porting a component, do not trim, normalize, or
isBlank-collapse a field before you have replicated every magic-value branch the legacy code relied on. Keep the exact comparisons ("".equals(raw)and" ".equals(raw)as separate cases) and treat the value as empty only where the original did. If you spot a sentinel like this, preserve parity and flag it; don't "fix" it without an explicit decision.
Both entries give people and AI tools the same instruction: check before changing behaviour. Here, that means checking how a field is used in existing content, even when its value looks like a mistake.
The dependencies AI didn’t find
Earlier this summer I worked with AI to add a Format field to our event template, with options for In-person, Online, or Hybrid. The template used that field to decide whether to show a campus location. Online events no longer needed one, and the event page displayed them correctly.
AI confidently told me the task was complete and verified. It hadn’t flagged that other components might need updating. Its answer treated the template as the boundary of the task, even though the same event information was used elsewhere.
When we searched beyond the template, we found five other places that still expected a campus location. The events calendar showed “Where: TBD” for online events, the campus filter’s Online option didn’t find them, and the public form for submitting events didn’t ask for a format at all. AI completed the change described in the spec, but that wasn’t the whole job.
I don’t need to know every dependency in advance, but I do need to make looking for them part of what “complete” means.
We put that expectation into the instruction file so it wouldn’t depend on remembering to ask each time. Here’s a shortened version:
When a new field changes how existing information is interpreted, trace where that information is read or written, even if the request names only one template or component. Look beyond matches for the field’s name. Before reporting the work done, list the dependencies you found, what was tested, and anything you couldn’t verify. Check forms that create the information as well as components that display it. Run the same check when fixing a bug caused by the change.
Technical instruction (abridged)
Property supersession sweep. Trigger: your change adds a property that overrides or replaces how an existing property is interpreted, or fixes one consumer of such a property. Do not let the task's framing decide: a request worded as a template or component change is still a data-model change when it alters what an existing property means, and the sweep applies regardless of how the work was described.
Before reporting the work done: start by searching the old property's name across the whole repo, plus its request-parameter and dialog-field spellings. Name matches are a starting point, not proof of coverage: follow aliases, shared helpers, dynamically constructed queries, and known integration boundaries where the value flows. Report any dependencies you cannot inspect or verify. Check the affected read and write paths with representative old and new data, and state what was actually tested.
Report every reader and writer you find, each with one of three dispositions: updated, unaffected (say why), or deferred (needs its own task). Never silently skip a consumer. Treat a writer that still produces an incompatible old shape as a blocker: it can keep reintroducing the old format after migration. Leave an old-format writer unchanged only when backward compatibility is intentional, documented, and verified for the affected readers; report that evidence explicitly.
The list gives us something to review beyond whether the requested template works. We can see which related components were checked and what still needs attention.
The modernization AI said was safe
We’re preparing our older components for AEM’s newer editing interface, Touch UI. Our content authors still work in Classic UI.
One component that holds other components was difficult to select and edit in Touch UI. AI recommended adding a setting that tells AEM to treat it as a container. That described what it did, so the recommendation made sense as a modernization step.
But the component still used the older rendering code. AI had recommended adding the setting without converting that code.
I asked several times whether the setting was safe and whether it could affect existing behaviour. The answers kept coming back reassuring, explaining why the setting was appropriate without accounting for how it would interact with the older code.
The recommended change fixed the selection problem in Touch UI, but AI hadn’t accounted for its effect on Classic UI, the interface our authors use every day. The component looked normal on the page. A colleague encountered the problem while adding content to a new container, when it no longer accepted components as expected. Our investigation pointed to an interaction between the new setting and the older code, something a visual check of the page wouldn’t reveal.
The correction was to remove the setting from the components still using the older code.
I thought I was reducing risk by asking AI again whether the change was safe. What I needed was to ask it to investigate what it hadn’t checked.
I was looking for reassurance, much as I might from a colleague. But asking “Are you sure?” can produce another explanation of the same answer without a new check behind it.
The more useful request is to investigate something the earlier answer hadn’t addressed. Here, I could have asked AI to trace how the setting interacted with the older code or compare the generated HTML before and after. We would still need to test the behaviour in Classic UI: could authors add, edit, and copy components? That would give us evidence to judge whether the change was safe.
I don’t have to know the answer in advance, but I do need to recognize where another check is needed. We added a rule for changes to component settings that affect the editing interface, so these checks wouldn’t depend on me remembering to ask. Here’s a shortened version:
Before shipping a change to component settings that affect the editor, test the component in both Classic UI and Touch UI. Check that authors can add, edit, and copy components, and configure which components are allowed. Repeated assurances from AI don’t replace checking the behaviour in the editing interface.
Technical instruction (abridged)
Before shipping component metadata that affects the editor (cq:isContainer, cq:noDecoration, cq:htmlTag, editConfig), exercise a page in both Classic UI and Touch UI: add, edit, copy/paste, and Design mode. Repeated AI reassurance that such a change is safe is not verification; only the author-side check adds evidence.
cq:isContainer on a JSP component that embeds a parsys changes the include decoration, so the generated name-based wrapper class its CSS and Classic UI authoring depend on disappears. The flag stays on the HTL components that handle their wrappers explicitly; the legacy JSP components take it back at HTL conversion together with an explicit cssClassName/decorationTagName wrapper.
From one fix to a shared instruction
These entries are part of the project instructions we keep in our repository and provide to our AI tools. They give our team and those tools a shared record of what we’ve learned about this system.
A comment can explain why a particular piece of code works the way it does. But a developer or AI tool working elsewhere in the codebase may never see it, even when the same lesson applies.
A shared instruction makes that lesson available across the codebase. The single-space workaround, for example, led us to a broader rule: before cleaning up an unusual field value, check whether anything relies on it.
That’s what we’re trying to capture in these entries: the specific experience and a check we can apply elsewhere. The event-template change led to a rule about checking every place that uses or saves the information, from the calendar displaying event details to the form collecting them. The container problem led to checks for editor settings across components. With more than 170 custom components in a thirteen-year-old system, we want a lesson from one component to help us recognize similar problems elsewhere.
Writing it down doesn’t guarantee that people or AI will follow it. It gives us something concrete to ask for and review, without having to remember every past incident in every new task.
The skill of writing good instructions
These instructions need regular review as the work changes. For example, a few times AI kept returning to the same recommendation and I couldn’t understand why. When I asked, it pointed to an instruction I’d written and forgotten about. That old guidance was still shaping its answers.
That review means deciding what to keep, revise, or remove. Rules can overlap or contradict each other, and guidance for one task doesn’t necessarily belong in every session. As the models change, we also need to reconsider which instructions still help. We can’t keep adding instructions and assume they’ll all be followed.
These examples have shaped how we write our instructions.
Make it checkable. “No em dashes or en dashes” can be verified with a text search. “Prioritize project value over user-pleasing” requires judgement. Where a check can be automated, the instruction should point to that check, so we can verify whether it was followed.
Write conditions, not commandments. Say when the instruction applies and what to check. For example: before changing how a field is displayed, check whether it is meant to carry HTML. That gives people and AI a specific action, rather than a general reminder to “be careful.”
Explain why it matters. When two rules pull against each other, a reason can help AI decide how to apply them. Our instructions require components to support both editing interfaces because more than 300 authors still rely on Classic UI. When we also ask AI to modernize the code, that explanation makes clear what the modernization needs to preserve.
Record what you ruled out. Our instructions include a “What not to recommend” section, with reasons for decisions such as converting older components as we work on them, rather than rewriting them all at once. Recording those decisions gives a new session context for why an apparently reasonable approach may not fit our system.
A developer unfamiliar with this system could miss these dependencies too. What stood out to me with AI was how confidently it could recommend a change without accounting for the behaviour around it. A sensible explanation made the change easier to trust, but didn’t establish that it was safe here.
We needed to understand why a single space had been saved in the content’s title field before changing how the code handled it. These dependencies weren’t always obvious in the code. Some were in saved content and in how people used the system.
Writing the code faster doesn’t mean we can spend less time testing it or thinking through dependencies and special cases.
Fixing the problem is part of the work. We also need to record what we learned in a way that helps people and AI know what to check next time.
I told some of these stories at CMS Connect 2026 in Montréal and on a Boye & Company member call. Here’s the recording of the call: